*Last verified against public documentation in November 2026.*
Executive Summary
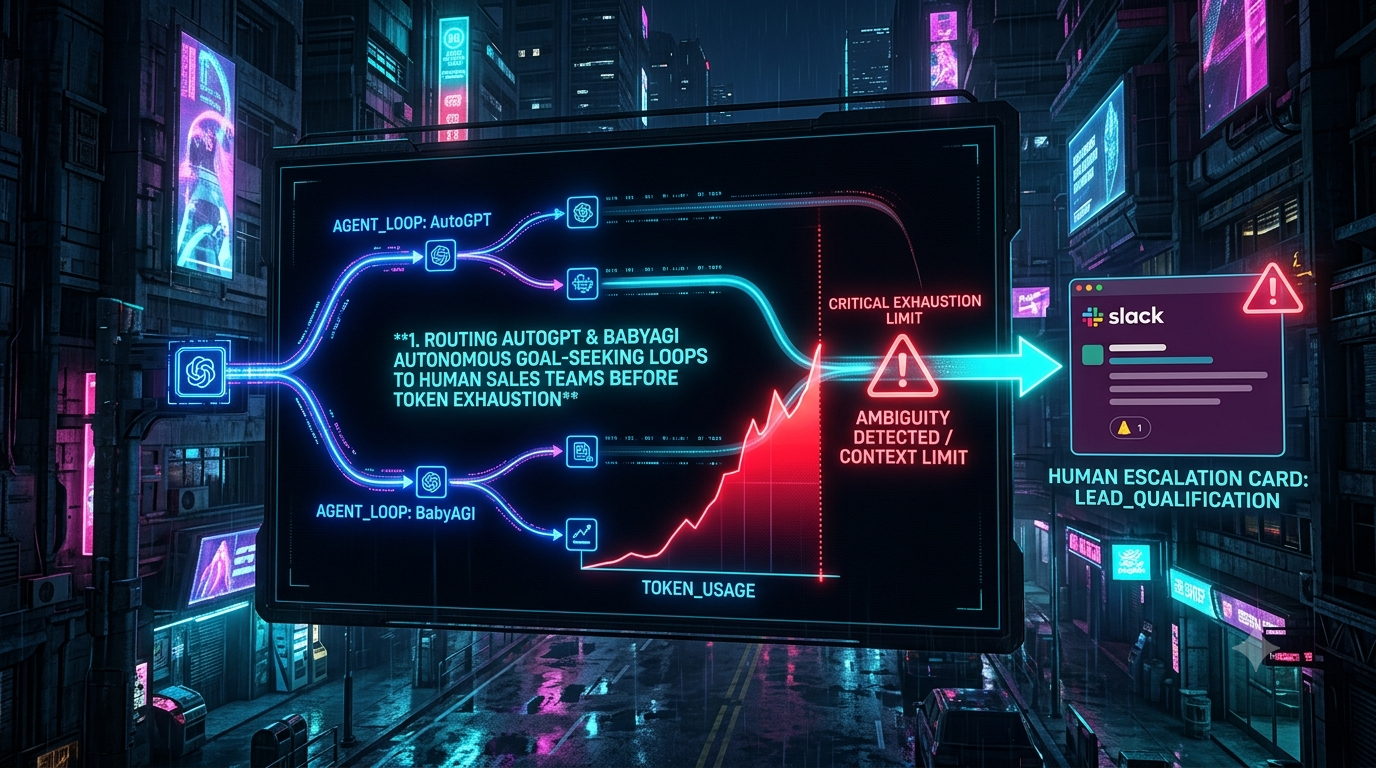
Autonomous goal-seeking loops are a natural fit for unstructured lead enrichment, company profiling, and buying-intent research. This guide uses the loops popularized by AutoGPT and BabyAGI as its reference pattern. Without deterministic guardrails, these recursive agents are prone to infinite loops, context degradation, and runaway token spend. They hit this wall on ambiguity such as complex parent-subsidiary hierarchies, missing executive contacts, or contradictory qualification signals.
Letting an agent burn through a large LLM budget without reaching a qualification verdict wastes money and puts your lead-response SLAs at risk.
This guide describes an intercept-and-escalate architecture. A guardrail layer monitors token consumption, step count, and confidence. When a limit is hit, the loop pauses and serializes its state. A Slack Block Kit message then lets a human sales rep resume the agent with guidance, take over the lead manually, or disqualify it.
A note on tooling. The original BabyAGI task-loop script (2023) was archived in September 2024, and the `yoheinakajima/babyagi` repository now hosts an experimental, function-based framework called *functionz*. AutoGPT has evolved from its original command-line experiment into the AutoGPT Platform, a builder and runtime for deploying agents. The failure modes and guardrails below apply to the *classic create-execute-prioritize loop pattern* that both projects made famous. They are framework-agnostic, and you can wire them into AutoGPT blocks, a custom loop, or a graph runtime such as LangGraph.
```
+-----------------------------------------------------------------------------------+
| AUTONOMOUS EXECUTION ENGINE |
| |
| [ Task Queue / Planner ] <---> [ Execution Loop (Tools, Search, Scraping) ] |
+-----------------------------------------------------------------------------------+
|
v
+-----------------------------------------------------------------------------------+
| GUARDRAIL INTERCEPTOR LAYER |
| |
| * Token Budget Threshold (>= 85% of budget) |
| * Loop Step Counter (>= max iterations) |
| * Low-Confidence Score (< threshold) |
+-----------------------------------------------------------------------------------+
|
(Threshold Exceeded)
v
+-----------------------------------------------------------------------------------+
| STATE SERIALIZATION & PAUSE |
| |
| * Pause the run |
| * Persist task queue, memory summary, and CRM context |
+-----------------------------------------------------------------------------------+
|
v
+-----------------------------------------------------------------------------------+
| SLACK ESCALATION BOT |
| |
| * Post Block Kit message with context, token metrics, and interactive buttons |
+-----------------------------------------------------------------------------------+
|
(Human action via Slack UI)
|
+------------------------------+------------------------------+
| | |
v v v
[ "Approve & Provide Context" ] [ "Manual Sales Takeover" ] [ "Disqualify Lead" ]
* Injects human guidance * Pushes lead to CRM * Marks lead disqualified
* Resumes the loop * Terminates agent run * Terminates agent run
```
1. Autonomous Agent Failure Modes in Lead Qualification
Autonomous agents run a cycle of task creation, execution, prioritization, and context updating. In B2B lead qualification, they fetch company records, scrape public pages, query search engines, parse filings, and cross-reference buyer personas.
```
+-----------------------------------------------------------------------------------+
| TYPICAL AUTONOMOUS AGENT LOOP |
| |
| +------------+ +---------------+ +------------------+ |
| | Execution | -----> | Task Creation | -----> | Prioritization | |
| | Loop | | & Expansion | | & Context Sync | |
| +------------+ +---------------+ +------------------+ |
| ^ | |
| +-------------------------------------------------+ |
+-----------------------------------------------------------------------------------+
```
Without deterministic intervention points, open-ended execution tends to fail in three ways.
A. Context Saturation and Token Exhaustion
Each tool call appends search results and scraped text to the agent’s working context. Two effects compound:
- Cost. Most LLM APIs bill input tokens on every call, and a naive loop resends the entire history each step. The history grows linearly, but *cumulative billed input tokens grow roughly quadratically* with the number of steps. Prompt caching reduces the price per token but not the underlying trend.
- Quality. Chroma’s 2025 “Context Rot” research tested 18 frontier models and found that every one degrades as input length grows, even well inside the advertised context window.
Hard limits add a further risk. When a request exceeds the model’s context window, the API rejects it or your framework truncates history. Either way, the agent can lose information it needs.
B. Recursive Execution Loops and Goal Drift
Non-standard lead profiles, such as holding companies, obscure domain structures, or conglomerates with deep parent-subsidiary trees, invite cyclical sub-tasks. A typical cycle looks like *“Find primary executive → search parent company → extract executive from parent → re-search subsidiary.”* Left unchecked, the agent spins on one account. A simple mitigation is to hash or normalize each new sub-task and escalate when the same task reappears.
C. The Low-Confidence Ambiguity Trap
Buyer signals are often subtle. An agent checking whether an account uses a particular software stack may find contradictory evidence across review sites and stale blog posts. With no hard stopping rule, it generates ever more speculative search tasks instead of accepting that the answer is ambiguous.
2. Architectural Blueprint: Guardrail Interceptors
Wrap the execution runtime, whether a custom loop, an AutoGPT-based agent, or a LangGraph graph, in a Guardrail Interceptor Middleware that runs after every step.
Core Escalation Criteria
Trigger an escalation when any of the following is true:
1. Token ceiling (T\_max). Accumulated prompt and completion tokens for one qualification run reach a set share of the budget, for example 85%.
2. Iteration cap (I\_max). The agent reaches N reasoning/action steps (for example, 12) without a final `QUALIFIED` or `DISQUALIFIED` status.
3. Ambiguity score (A\_score). A confidence score from an evaluation prompt falls below a threshold, for example 0.70.
These numbers are starting points. Tune them against your own cost data and accuracy requirements. Also note that an LLM’s self-reported confidence is only a rough signal. Calibrate it against human-labeled outcomes before relying on it.
State Persistence Engine
When a rule fires, the runtime should not simply kill the process. It must serialize enough state for a human to inspect the run and for the agent to resume. Store it in a durable store such as Redis, PostgreSQL, or DynamoDB.
If you build on LangGraph, much of this is built in. Its `interrupt()` function pauses a graph at any node, saves state through a checkpointer, and waits until you resume with `Command(resume=...)`. Use a durable checkpointer in production, and resume with the same thread ID.
An illustrative schema:
```
{
"session_id": "sess_agent_b2b_984211",
"lead_id": "lead_corp_77102",
"company_name": "Acme Enterprise Solutions",
"status": "PAUSED_PENDING_HUMAN_INTERVENTION",
"trigger_reason": "TOKEN_BUDGET_THRESHOLD_EXCEEDED",
"metrics": {
"tokens_used": 114500,
"max_token_budget": 128000,
"iterations_completed": 11,
"confidence_score": 0.58
},
"current_context_summary": "Identified 3 potential VP-level buyers, but corporate structure shows dual headquarters in London and NYC. Buyer region is ambiguous.",
"task_queue": [
"Verify whether the NYC or London office handles software procurement.",
"Draft personalized outreach to VP of Infrastructure."
],
"scraped_sources": [
"https://acme.example.com/about",
"https://linkedin.example.com/company/acme"
]
}
```
3. Designing the Interactive Escalation Card in Slack
When a loop pauses, post a message built with Slack’s Block Kit. The card should give an account executive or SDR enough context to decide in seconds.
Keep these Block Kit limits in mind when generating the payload dynamically:
- Header text: 150 characters.
- Section text: 3,000 characters.
- Section fields: up to 10, each up to 2,000 characters.
- Button label: 75 characters.
- Button `value`: 2,000 characters.
- `action_id` and `block_id`: 255 characters.
- Actions block: up to 25 elements.
Truncate agent summaries to fit these limits. Pass only a session ID in a button’s `value` and keep the full state in your own store.
Block Kit Payload (for `chat.postMessage`)
```
{
"channel": "C0812345678",
"text": "⚠️ Agent escalation required: Acme Enterprise Solutions",
"blocks": [
{
"type": "header",
"text": {
"type": "plain_text",
"text": "⚠️ Autonomous Agent Escalation | Lead Qualification",
"emoji": true
}
},
{
"type": "section",
"fields": [
{ "type": "mrkdwn", "text": "*Account:* Acme Enterprise Solutions" },
{ "type": "mrkdwn", "text": "*Target Domain:* acme.example.com" },
{ "type": "mrkdwn", "text": "*Reason:* Token budget threshold exceeded (89%)" },
{ "type": "mrkdwn", "text": "*Confidence Score:* 0.58 (low)" }
]
},
{ "type": "divider" },
{
"type": "section",
"text": {
"type": "mrkdwn",
"text": "*Agent reasoning & context summary:*\n> Found 3 potential VP-level buyers but conflicting headquarters information (London vs. New York). Could not determine the regional purchasing owner within the token budget."
}
},
{
"type": "section",
"text": {
"type": "mrkdwn",
"text": "*Pending task queue:*\n1. Verify regional purchasing decision maker.\n2. Execute outbound outreach sequence."
}
},
{ "type": "divider" },
{
"type": "actions",
"block_id": "agent_escalation_actions",
"elements": [
{
"type": "button",
"text": { "type": "plain_text", "text": "Approve & Provide Context", "emoji": true },
"style": "primary",
"value": "sess_agent_b2b_984211",
"action_id": "btn_provide_context"
},
{
"type": "button",
"text": { "type": "plain_text", "text": "Manual Sales Takeover", "emoji": true },
"style": "danger",
"value": "sess_agent_b2b_984211",
"action_id": "btn_manual_takeover"
},
{
"type": "button",
"text": { "type": "plain_text", "text": "Disqualify Lead", "emoji": true },
"value": "sess_agent_b2b_984211",
"action_id": "btn_disqualify"
}
]
}
]
}
```
4. Reference Implementation
The Python below is a minimal sketch. It uses `slack_sdk` to post the card, and FastAPI to receive Slack interactions. Install the dependencies with `pip install fastapi slack_sdk httpx python-multipart`.
You will need a Slack app with a bot token, Interactivity enabled, and a Request URL pointing at your `/slack/interactive` endpoint. Slack sends every interaction there.
Step 1: Interceptor Runtime (`agent_runner.py`)
```
import os
from typing import Any, Dict, List, Tuple
from slack_sdk import WebClient
slack = WebClient(token=os.environ["SLACK_BOT_TOKEN"])
ESCALATION_CHANNEL = os.environ["SLACK_ESCALATION_CHANNEL"]
MAX_TOKEN_BUDGET = 100_000
TOKEN_ALERT_RATIO = 0.85
MAX_ITERATIONS = 12
CONFIDENCE_THRESHOLD = 0.70
Use Redis/PostgreSQL (or a LangGraph checkpointer) in production.
STATE_STORE: Dict[str, Dict[str, Any]] = {}
class ExecutionState:
def __init__(self, session_id: str, lead_id: str, company_name: str):
self.session_id = session_id
self.lead_id = lead_id
self.company_name = company_name
self.tokens_used = 0
self.iterations = 0
self.confidence_score = 1.0
self.summary = ""
self.task_queue: List[str] = []
self.status = "RUNNING"
def check_guardrails(state: ExecutionState) -> Tuple[bool, str]:
if state.tokens_used >= MAX_TOKEN_BUDGET * TOKEN_ALERT_RATIO:
return True, f"TOKEN_BUDGET_THRESHOLD ({state.tokens_used}/{MAX_TOKEN_BUDGET} tokens)"
if state.iterations >= MAX_ITERATIONS:
return True, f"MAX_ITERATIONS_REACHED ({state.iterations}/{MAX_ITERATIONS} steps)"
if state.confidence_score < CONFIDENCE_THRESHOLD:
return True, f"LOW_CONFIDENCE ({state.confidence_score:.2f} < {CONFIDENCE_THRESHOLD})"
return False, ""
def trigger_slack_escalation(state: ExecutionState, reason: str) -> None:
state.status = "PAUSED_PENDING_HUMAN"
STATE_STORE[state.session_id] = state.__dict__
blocks = [
{"type": "header",
"text": {"type": "plain_text", "text": "⚠️ Escalation Triggered | Autonomous Sales Loop"}},
{"type": "section", "fields": [
{"type": "mrkdwn", "text": f"*Account:* {state.company_name}"},
{"type": "mrkdwn", "text": f"*Session ID:* `{state.session_id}`"},
{"type": "mrkdwn", "text": f"*Trigger:* {reason}"},
{"type": "mrkdwn", "text": f"*Tokens used:* {state.tokens_used:,}"},
]},
{"type": "section",
"text": {"type": "mrkdwn",
"text": f"*Current agent summary:*\n>{state.summary[:2500]}"}},
{"type": "actions", "block_id": "escalation_controls", "elements": [
{"type": "button", "style": "primary", "action_id": "btn_provide_context",
"text": {"type": "plain_text", "text": "Approve & Provide Context"},
"value": state.session_id},
{"type": "button", "style": "danger", "action_id": "btn_manual_takeover",
"text": {"type": "plain_text", "text": "Manual Sales Takeover"},
"value": state.session_id},
{"type": "button", "action_id": "btn_disqualify",
"text": {"type": "plain_text", "text": "Disqualify Lead"},
"value": state.session_id},
]},
]
slack.chat_postMessage(
channel=ESCALATION_CHANNEL,
text=f"⚠️ Agent escalation: {state.company_name}",
blocks=blocks,
)
print(f"[SYSTEM] Paused {state.session_id}; escalation sent to Slack.")
def run_autonomous_loop(session_id: str, lead_id: str, company: str) -> None:
state = ExecutionState(session_id, lead_id, company)
Simulated iterations standing in for real tool-calling steps.
simulated_steps = [
{"tokens": 25_000, "conf": 0.95, "summary": "Fetched landing page and pricing tier."},
{"tokens": 35_000, "conf": 0.85, "summary": "Identified company size and tech stack."},
{"tokens": 30_000, "conf": 0.55, "summary": "Ambiguous regional decision maker; found 2 conflicting profiles."},
]
for step in simulated_steps:
state.iterations += 1
state.tokens_used += step["tokens"]
state.confidence_score = step["conf"]
state.summary = step["summary"]
should_escalate, reason = check_guardrails(state)
if should_escalate:
trigger_slack_escalation(state, reason)
return # Stop until a human resolves the escalation
state.status = "COMPLETED"
print(f"[SYSTEM] Agent completed qualification for {company}.")
```
Step 2: Interactive Listener (`slack_listener.py`)
Slack requires an HTTP 200 acknowledgment within 3 seconds of every interaction payload. This listener therefore acknowledges first and does slow work (CRM calls, resuming the agent) in the background. It also verifies Slack’s request signature before trusting anything in the payload.
```
import hashlib
import hmac
import json
import os
import time
from urllib.parse import parse_qs
import httpx
from fastapi import BackgroundTasks, FastAPI, HTTPException, Request, Response
app = FastAPI()
SIGNING_SECRET = os.environ["SLACK_SIGNING_SECRET"]
Slack user IDs allowed to act on escalations (use a group/role lookup in production)
AUTHORIZED_USER_IDS = set(filter(None, os.getenv("AUTHORIZED_SLACK_USER_IDS", "").split(",")))
def verify_slack_signature(body: bytes, timestamp: str, signature: str) -> bool:
try:
if abs(time.time() - int(timestamp)) > 60 * 5: # reject replays older than 5 minutes
return False
except ValueError:
return False
base = b"v0:" + timestamp.encode() + b":" + body
expected = "v0=" + hmac.new(SIGNING_SECRET.encode(), base, hashlib.sha256).hexdigest()
return hmac.compare_digest(expected, signature)
async def update_message(response_url: str, text: str) -> None:
async with httpx.AsyncClient() as client:
await client.post(response_url, json={"replace_original": True, "text": text})
@app.post("/slack/interactive")
async def handle_slack_interaction(request: Request, background: BackgroundTasks):
raw_body = await request.body()
if not verify_slack_signature(
raw_body,
request.headers.get("X-Slack-Request-Timestamp", ""),
request.headers.get("X-Slack-Signature", ""),
):
raise HTTPException(status_code=401, detail="Invalid Slack signature")
payload = json.loads(parse_qs(raw_body.decode())["payload"][0])
actions = payload.get("actions", [])
if not actions:
return Response(status_code=200)
user_id = payload["user"]["id"]
if AUTHORIZED_USER_IDS and user_id not in AUTHORIZED_USER_IDS:
background.add_task(
update_message, payload["response_url"],
f"⛔ <@{user_id}> is not authorized to act on agent escalations.",
)
return Response(status_code=200)
action_id = actions[0]["action_id"]
session_id = actions[0]["value"]
response_url = payload["response_url"]
if action_id == "btn_provide_context":
In production: call views.open with payload["trigger_id"] (valid ~3 seconds)
to collect guidance in a modal, then resume the agent on view_submission.
background.add_task(
update_message, response_url,
f"✅ <@{user_id}> is providing guidance for session `{session_id}`. Resuming the loop.",
)
elif action_id == "btn_manual_takeover":
In production: create the CRM lead/task (Salesforce, HubSpot, ...) and terminate the run.
background.add_task(
update_message, response_url,
f"🛑 <@{user_id}> took over session `{session_id}`. Agent stopped; lead routed to the sales pipeline.",
)
elif action_id == "btn_disqualify":
background.add_task(
update_message, response_url,
f"🗑️ <@{user_id}> disqualified the lead for session `{session_id}`.",
)
return Response(status_code=200)
```
Three details worth knowing:
- Use `user.id` and mention people with `<@USER_ID>`. Slack has deprecated `@username` handles, so relying on `user.username` for display is fragile.
- A `response_url` can be used up to 5 times within 30 minutes. If an escalation may sit for hours, post with `chat.postMessage` and update the card later with `chat.update` instead of relying on `response_url`.
- A `trigger_id`, which opens modals through `views.open`, is short-lived (about 3 seconds). Acknowledge, call `views.open` immediately, then do any heavy work.
5. Bidirectional State Synchronization and Recovery
```
HUMAN SELECTION IN SLACK
|
+-------------------------+-------------------------+
| |
[ Approve & Provide Context ] [ Manual Sales Takeover ]
| |
v v
Open modal / collect directives Terminate agent instance
| |
v v
Inject guidance into context Package partial metadata
| |
v v
Compact history, grant bounded budget Create CRM task & assign owner
| |
v v
Resume execution loop Log audit trail & end run
```
Path A: Inject Guidance and Resume
1. The button click opens a Slack modal asking for the missing information (for example, *“Target region: North America”*).
2. The submitted text becomes a high-priority directive added to the agent’s context.
3. Rather than resetting counters to a full budget, compact the accumulated history into a summary and grant a *bounded* additional allowance. A full reset invites the same failure to repeat. Compaction, meaning summarizing settled steps into a short progress note, also cuts both cost and context-rot risk.
Path B: Immediate Manual Takeover
1. The engine receives a terminate signal and stops the run.
2. Partial results, including company data, executive names, source links, and the agent’s confidence notes, are packaged into a CRM record (such as a Salesforce Lead or HubSpot contact).
3. The lead is assigned to a rep’s queue, and an audit-trail entry records that a human escalation occurred.
6. Operational Best Practices
Metrics to Track
The targets below are illustrative starting points, not industry standards. Baseline your own pipeline first and adjust.
| Metric | Example starting target | Why it matters |
|---|---|---|
| Escalation rate | Set from your baseline; review weekly | Too high means thresholds are too tight or the agent is underperforming. Too low may mean ambiguous accounts are running unmonitored. |
| Time to human resolution | A short, explicit SLA (for example, 15 minutes during business hours) | Keeps lead response times intact when an agent hands off. |
| Token cost per qualified lead | A hard cap per run | Stops edge cases from dominating spend. |
| State-restoration fidelity | Verified by automated tests | Confirms no scraped or enriched data is lost across pause and resume. |
Security and Reliability Guidelines
- Verify every Slack request. Check the `X-Slack-Signature` and `X-Slack-Request-Timestamp` headers against your signing secret, and reject stale timestamps (for example, older than 5 minutes). Do not use `trigger_id` as an authorization check. It only opens modals.
- Authorize the human. Map Slack user IDs to roles so that only permitted account executives can trigger takeovers or CRM writes.
- Use durable waits. A single AWS Lambda invocation can run for at most 15 minutes, so don’t hold a function open waiting for a human. Options that survive long waits include:
- LangGraph interrupts with a durable checkpointer.
- Temporal, via Signals.
- Trigger.dev, via waitpoints that pause a run without consuming compute.
- AWS Lambda durable functions, which allow executions of up to one year.
- Set a state TTL and fallback. For example, if no one responds within 24 hours, convert the partial lead into a CRM task so it isn’t lost. Pick the window to match your sales cadence.
- Detect repeated work. Normalize and hash sub-tasks, and escalate when the agent re-queues the same one.
References
- AutoGPT repository and release notes: <https://github.com/Significant-Gravitas/AutoGPT>
- BabyAGI repository and archive notice: <https://github.com/yoheinakajima/babyagi>
- Slack, handling user interaction (3-second acknowledgment, `response_url` limits): <https://docs.slack.dev/interactivity/handling-user-interaction>
- Slack `block_actions` payload reference: <https://docs.slack.dev/reference/interaction-payloads/block_actions-payload>
- LangGraph human-in-the-loop and interrupts: <https://docs.langchain.com/oss/python/langgraph/human-in-the-loop>
- Trigger.dev waits and waitpoints: <https://trigger.dev/docs/wait.md>
- AWS Lambda durable functions: <https://docs.aws.amazon.com/lambda/latest/dg/durable-basic-concepts.html>
- Agent-loop token cost growth: <https://augmentcode.com/guides/ai-agent-loop-token-cost-context-constraints>